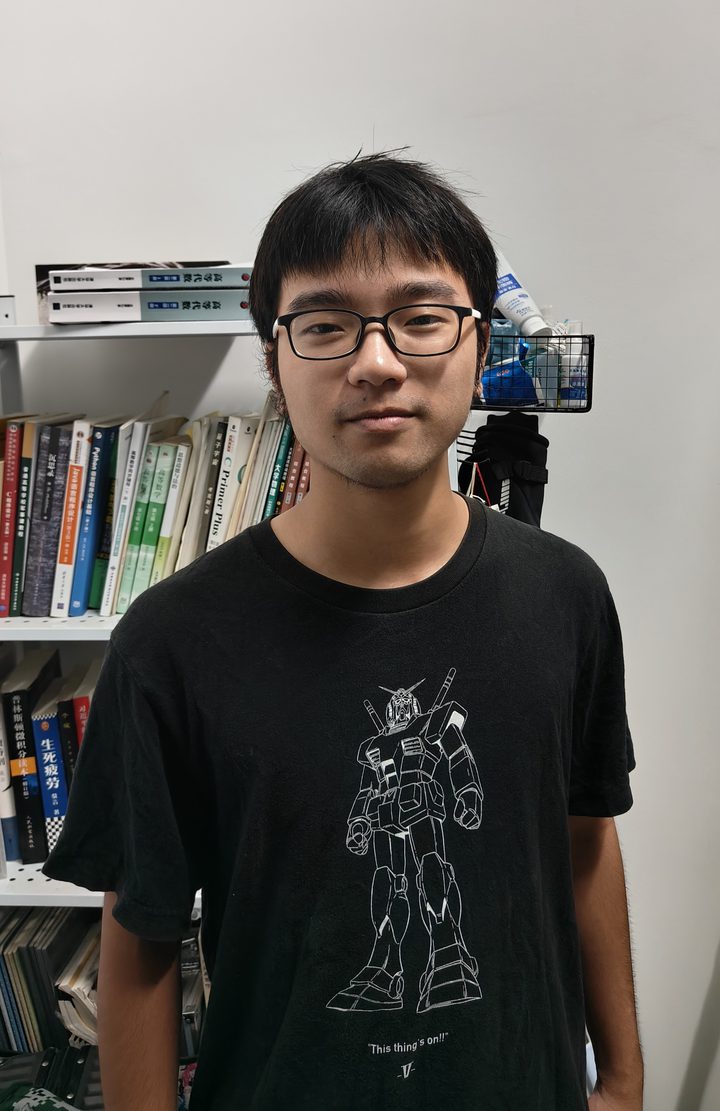
About / 个人简介
I am a 2023-cohort undergraduate in the Radio Wave Propagation and Antennas Honors Program at the School of Physics, Xidian University, and expect to graduate in July 2027. My research lies at the intersection of multimedia signal processing and artificial intelligence, with a focus on multimodal generation and understanding, deepfake speech detection, model generalization, and interpretability.
I have been admitted to the Ph.D. program in the Department of Engineering Physics at Tsinghua University and will be advised by Prof. Junjie Zhang. My previous research experience includes studying the generalization of deepfake speech detectors across speech-generation paradigms in Academician Xiaoping Zhang’s group, leading the VMM research on video-to-music generation as first author, and contributing to HumanMAC++ on diffusion-based human motion prediction.
Research Interests
- Trustworthy multimedia intelligence(可信多媒体智能): deepfake speech detection, out-of-distribution generalization, failure analysis, and model interpretability.
- Multimodal generation and understanding(多模态生成与理解): video-to-music generation, audiovisual semantic and affective alignment, and generative models.
- Physics-inspired foundations of large models(物理启发的大模型理论基础): exploring physical principles for energy-efficient LLMs and AGI-oriented learning systems, while using mathematical tools to formulate rigorous, operational definitions of intelligence.
News
- October 2026: Received the National Scholarship for Undergraduate Students (Top 1%).
- September 2026: Submitted What survives the codec shift: Pooled no-vocals residuals for speech deepfake detection to ICASSP 2027.
- May 2026: Received an Honorable Mention in the Mathematical Contest in Modeling (MCM).
- March 2026: Joined Xiaoping Zhang's group at Tsinghua University to work on deepfake speech detection.
- October 2025: The first-author VMM paper became available online in Computer Vision and Image Understanding.
- 2024: Received the National Scholarship for Undergraduate Students and the Outstanding Student Model honor at Xidian University.
Publications
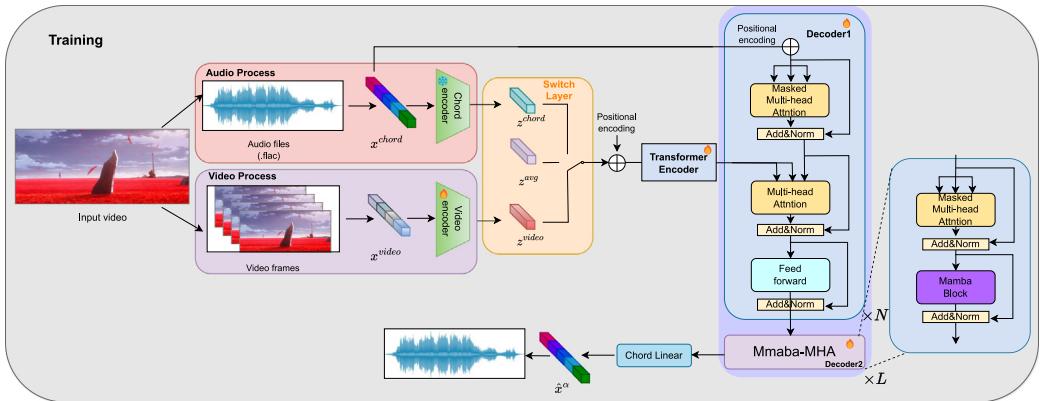
VMM: Video-Music Mamba for Generating Background Music from Videos
Jiajun Xu, Zixiang Lu, Ping Gao, Qiguang Miao, Kun Xie
Xidian University
Computer Vision and Image Understanding, 262, Article 104545, December 2025.
VMM combines Mamba and Transformer components for video-to-music generation, coordinating video and chord conditioning with a Switch Schedule.
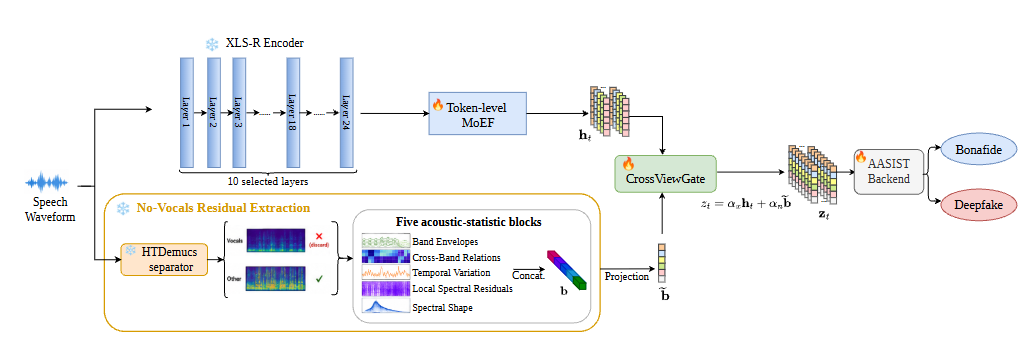
What Survives the Codec Shift: Pooled No-Vocals Residuals for Speech Deepfake Detection
Jiajun Xu, Menglu Li, Xiao-Ping Zhang
Tsinghua University
arXiv preprint, arXiv:2609.33375, September 2026.
MN-P combines pooled no-vocals residuals with token-level XLS-R features through adaptive gating for codec-unseen speech deepfake detection.
Research
Deepfake Speech Detection
Research Intern, Xiaoping Zhang’s Group, Tsinghua University | March 2026 - September 24, 2026
I studied how deepfake speech detectors generalize across speech-generation paradigms. The work developed controlled evaluation and representation-diagnostic procedures and explored multi-layer speech representations with Mixture of Experts integration for unseen codec conditions.
VMM: Video-Music Mamba
First Author | June 2024 - November 2025
I led the problem formulation, literature review, method design, experiments, visualization, and paper writing for video-to-music generation. The project investigates visual semantics, temporal structure, and affective alignment in generated music.
HumanMAC++
Research Intern, Tsinghua University | September 2023 - December 2023
I contributed to experimental validation for diffusion-based human motion prediction and studied the SDE view that unifies NCSN and DDPM, together with the DDNM method.
Diffusion-Model-Based Mural Restoration Platform
Project Lead, National Undergraduate Innovation and Entrepreneurship Training Program
I led the team through literature study, method design, model reproduction, system implementation, debugging, and final presentation. The project completed its planned review and explored generative models for digital cultural-heritage restoration.
Education
Tsinghua University
Incoming Ph.D. Student, Department of Engineering Physics | Expected Enrollment: 2027
Xidian University
B.Sc. Student, Radio Wave Propagation and Antennas Honors Program | 2023 - Expected July 2027
- GPA: 3.84/4.00
- Rank: 1/33 (final program ranking)
Honors and Awards
- 2026 National Scholarship for Undergraduate Students (Top 1%)
- 2026 Mathematical Contest in Modeling (MCM), Honorable Mention
- 2024 Interdisciplinary Contest in Modeling (ICM), Honorable Mention
- 2024 National Scholarship for Undergraduate Students (Top 1%)
- 2024 Outstanding Student Model, Xidian University
Last updated: October 2026